
👋 About me
- I am a direct Ph.D. student in Electronic Information at Harbin Institute of Technology (HIT), advised by Prof. Tonghua Su. I expect to graduate in Jun. 2029.
- I received my Bachelor’s Degree in Software Engineering at Central South University in Jun. 2024.
- My research focuses on agent memory and recursive self-improvement (RSI) in multi-agent systems (MAS). I also work on generating digital human videos with physiologically plausible motion.
- I am actively seeking research discussion and collaboration opportunities, so feel free to contact me!

🔥 News
- 2026.10: 🏅 Selected for the National Scholarship for Doctoral Students at Harbin Institute of Technology.
- 2026.09: 🎉🎉 Our paper “DH-OmniFace” has been accepted with mandatory minor revisions by IEEE Transactions on Multimedia. (CCF-A, First Author)
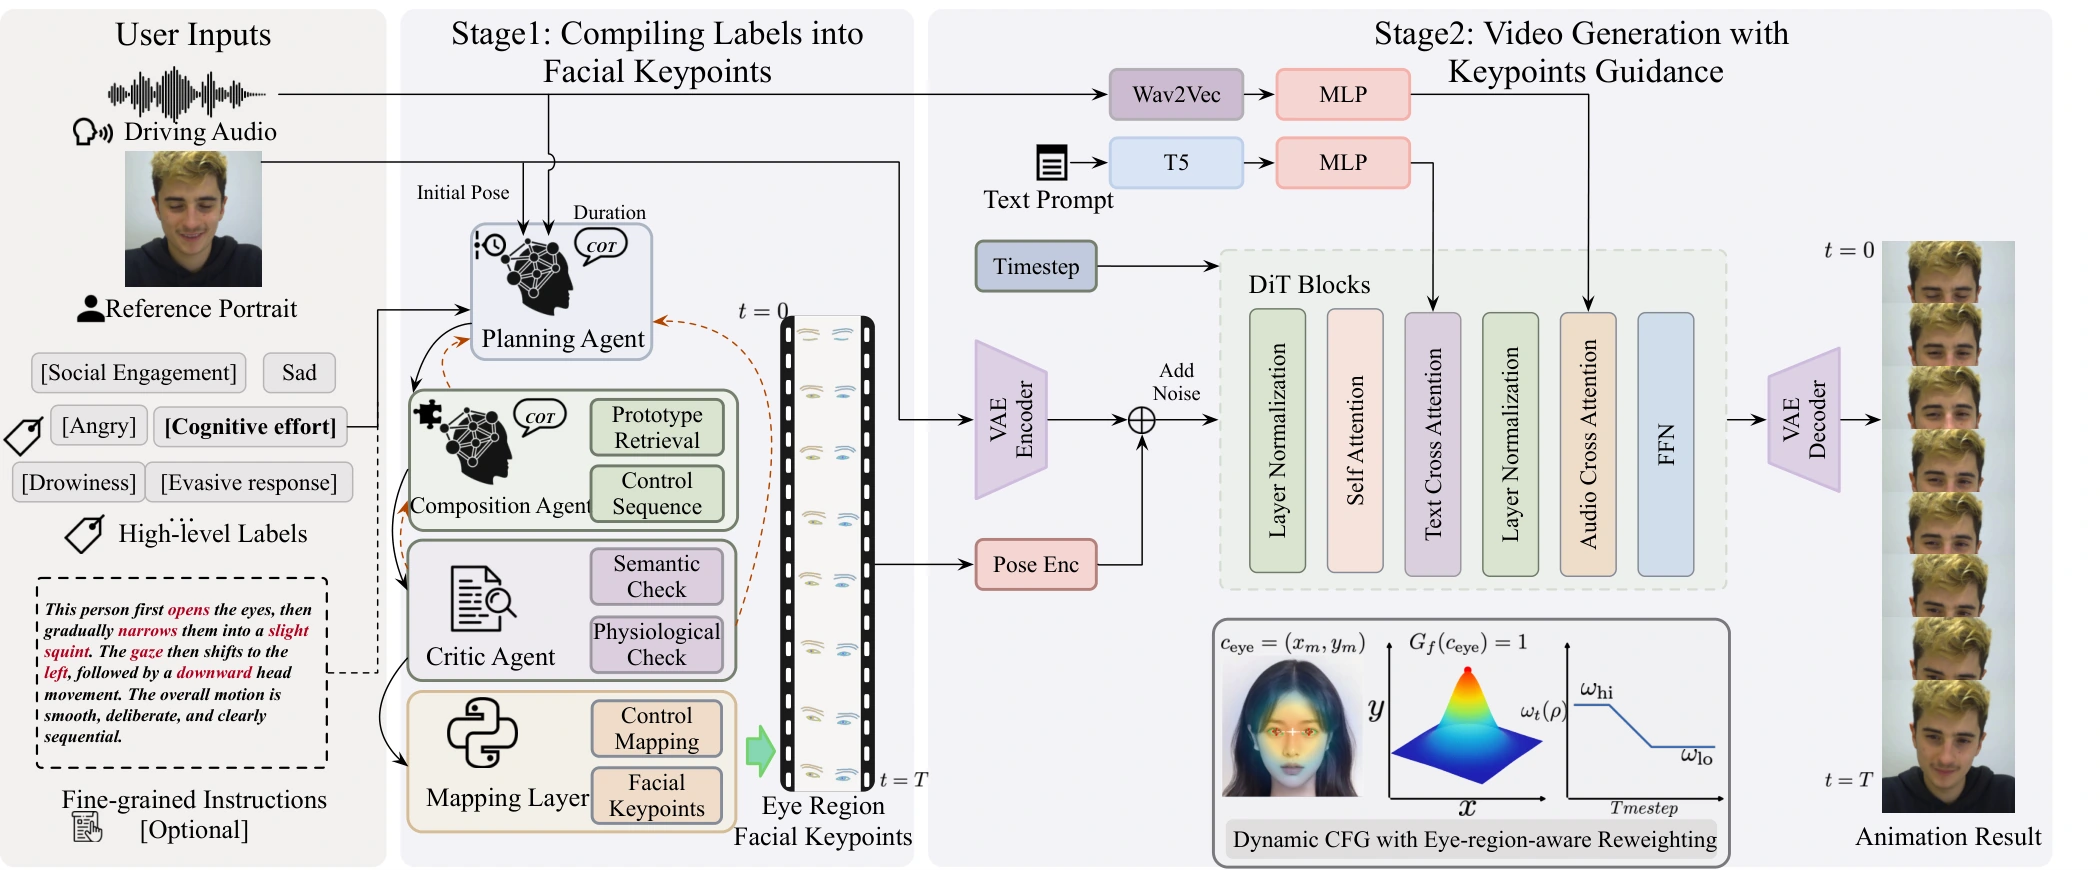
- 2026.07: 🎉🎉 Our paper “CogPortrait: Fine-Grained Eye-Region Control in Portrait Animation via Hierarchical Agent Planning” has been accepted by ACM MM 2026. (CCF-A, First Author)
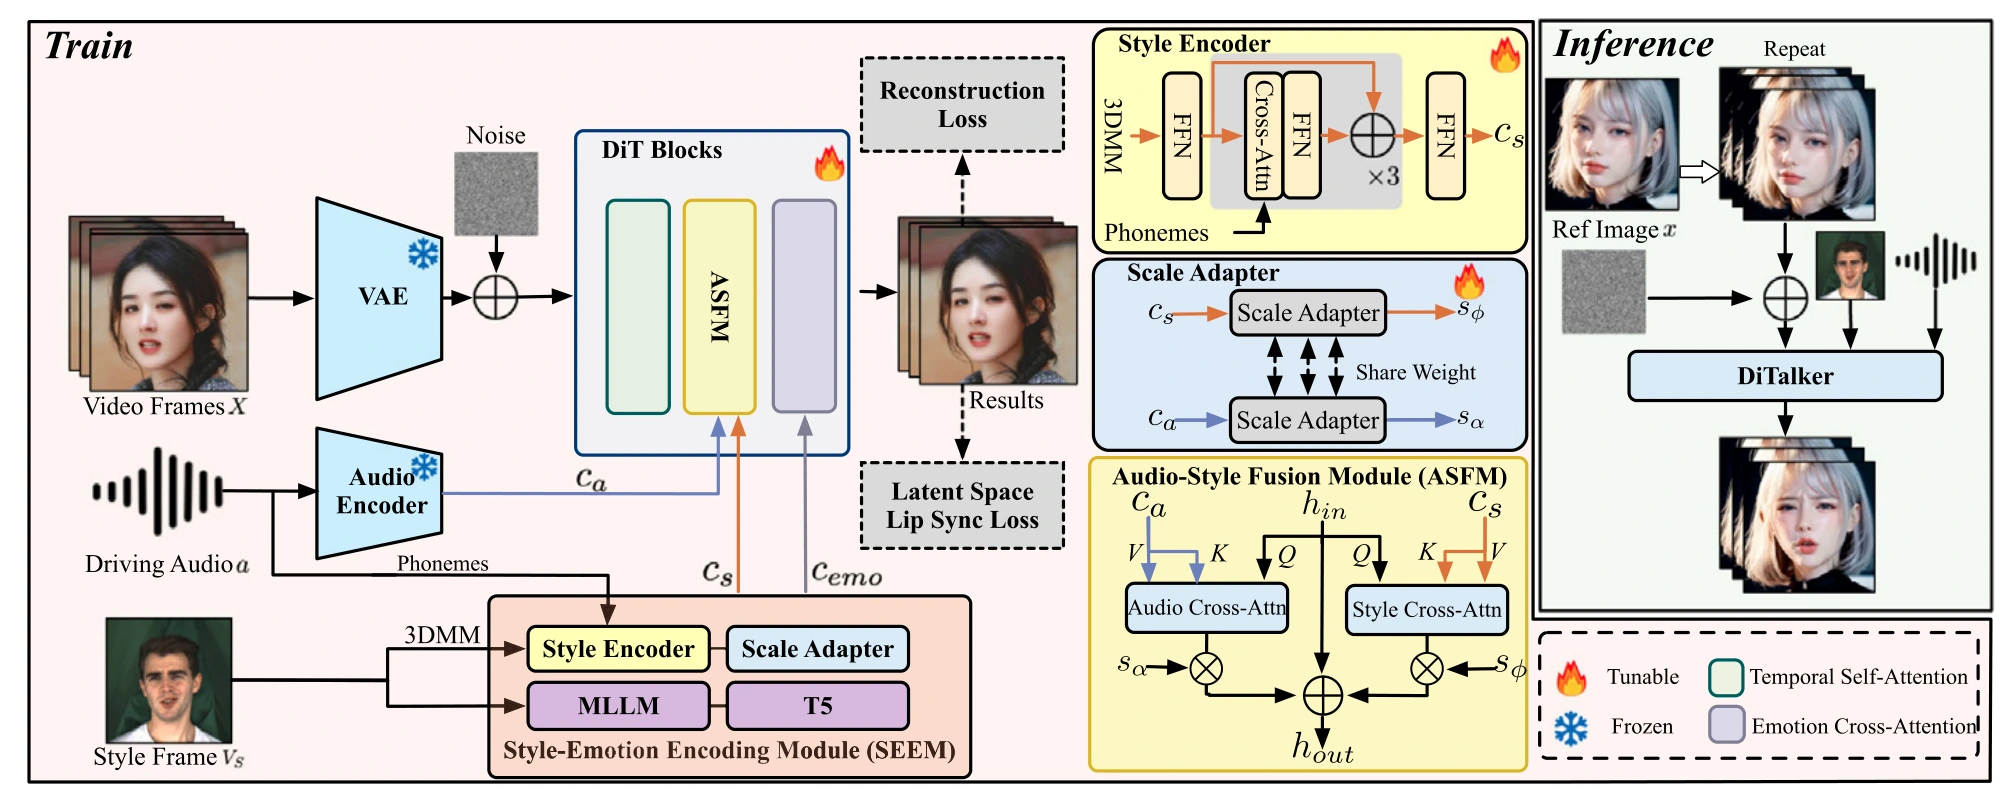
- 2026.05: 🎉🎉 Our paper “DiTalker: A unified DiT-based framework for high-quality and style-controllable portrait animation” was accepted by Computer Vision and Image Understanding. (CCF-B, First Author)
- 2025.12: 🎉🎉 Served as an organizer for the ACM Multimedia Asia 2025 Grand Challenge on Multimodal Multiethnic Talking-Head Video Generation.
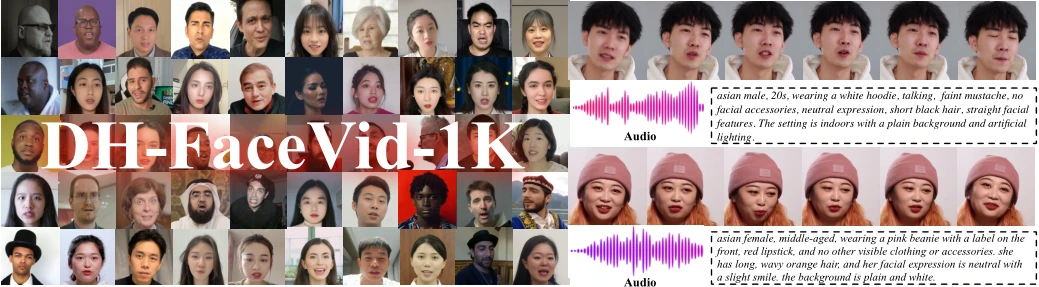
- 2025.06: 🎉🎉 Our paper “DH-FaceVid-1K: A Large-Scale High-Quality Dataset for Face Video Generation” has been accepted by ICCV 2025. (CCF-A, Second Author)
- 2024.07: 💼 Started Algorithm Internship at Digital Human Group, Li Auto.
- 2024.06: 🎓 Received my Bachelor of Engineering in Software Engineering from Central South University.
📝 Publications
2026
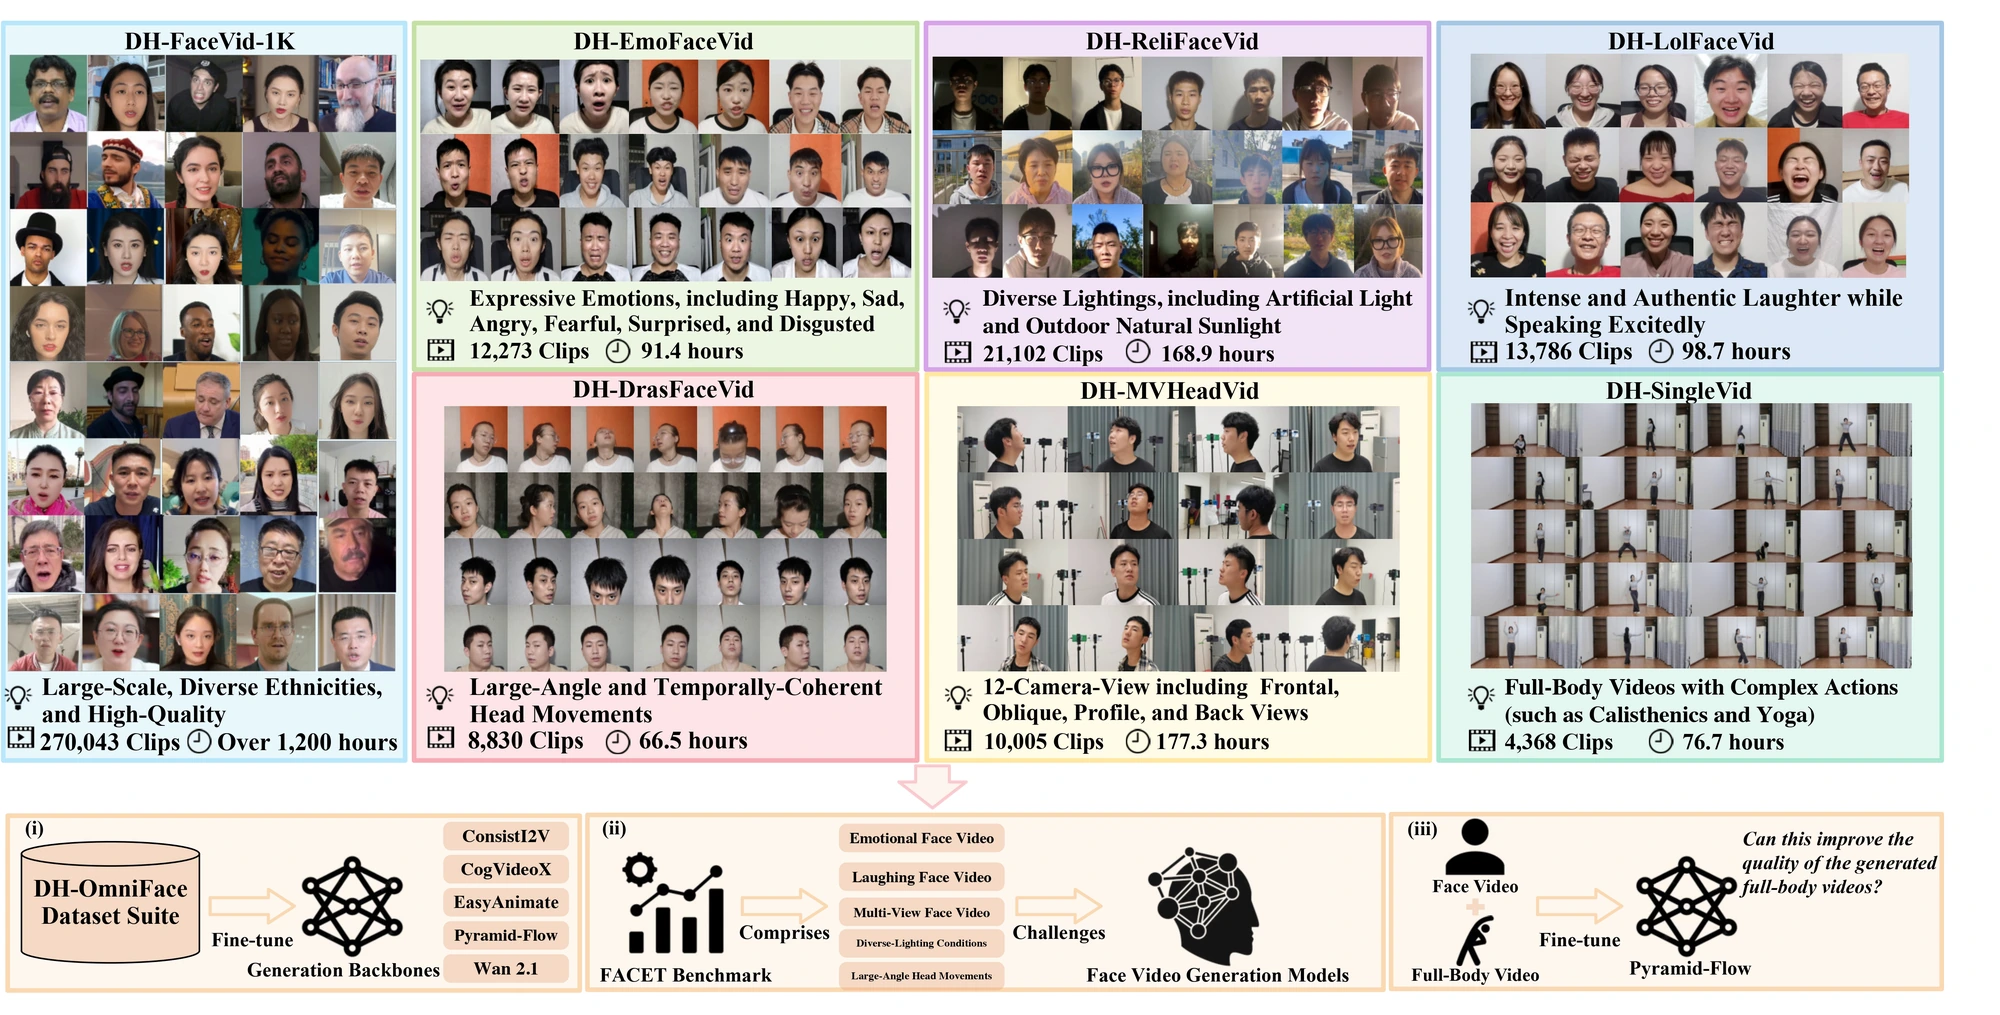
DH-OmniFace: A Large-Scale and Multi-Attribute Dataset Suite for Controllable Face Video Generation
He Feng et al.
IEEE Transactions on Multimedia · CCF-A
Accepted with mandatory minor revisions (AQ)
2025
Current Research
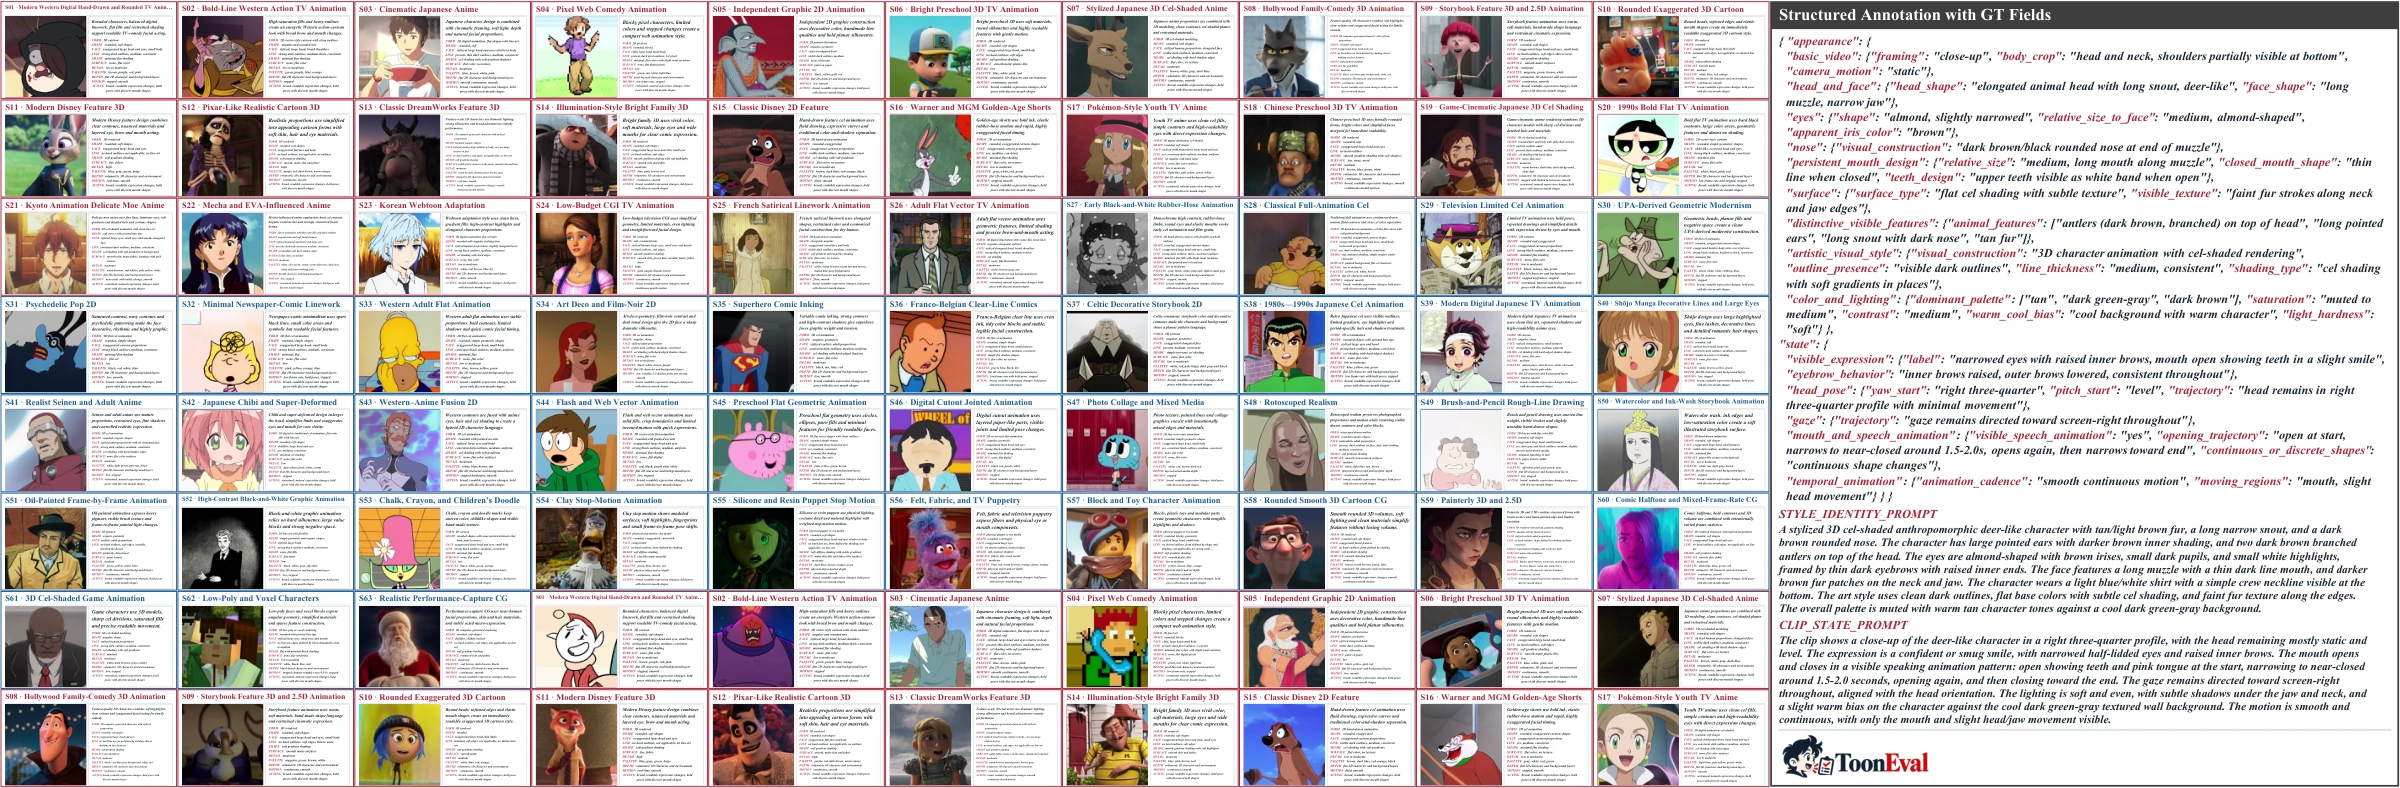
ToonEval: A Diagnostic Benchmark for Cartoon Talking Portraits
He Feng*, Xiangyang Shi*, Yongjia Ma, Kun Wang, Haoxuan Ge, Ran Li, Tonghua Su (* Equal contribution)
ToonEval evaluates character design, rendering style, part depiction, temporal stability, and motion fidelity in generated cartoon talking portraits.
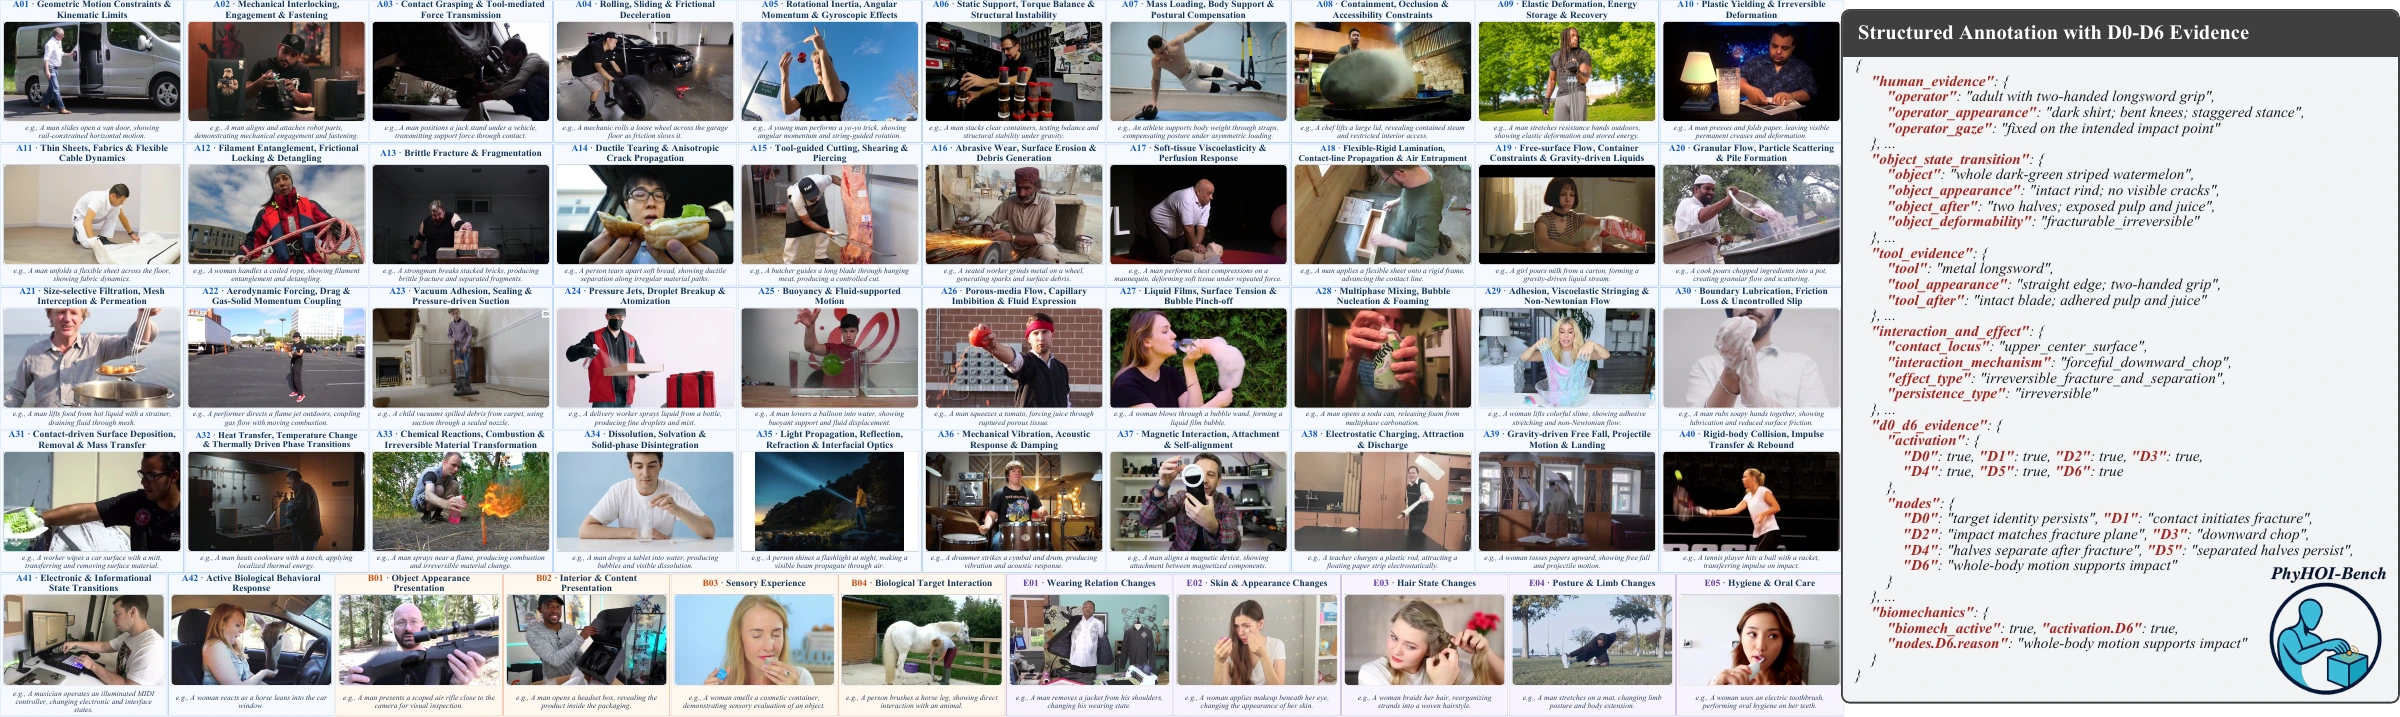
PhyHOI-Bench: Diagnosing Physical Plausibility in Third-Person Human-Object Interaction Video Generation
He Feng (First Author)
PhyHOI-Bench uses causal annotations to identify where generated human-object interactions depart from physically plausible behavior.
Under Review
TPAMITalking Face Video Generation Survey, et al. (Contributor)
📜 Patents
- Two accepted internal invention patents on talking-face generation and digital human foundation models.
- Method and System for Automatic Generation of Multilingual Educational Videos Based on Multi-Agent Collaboration — Accepted.
- Multi-language MOOC Teaching Video Automatic Generation System Based on Multi-Agent Collaboration — Software Copyright.
🎓 Educations
- Sep. 2024 – Jun. 2029, Harbin Institute of Technology, Direct Ph.D. in Electronic Information, Advisor: Prof. Tonghua Su
- Sep. 2020 – Jun. 2024, Central South University, B.Eng. in Software Engineering
💼 Internships
Algorithm Intern · Advanced Computing Research Group
Spring Research Institute, China Electronics Corporation · Sep. 2026 – Present · Shenzhen, China
Algorithm Intern · Digital Human Group, Li Auto
Jul. 2024 – Jan. 2025 · Beijing, China
- Reproduced and evaluated 20+ talking-face generation models (SadTalker, AniPortrait, EMO, MuseV, VASA-1, MODA).
- Developed and evaluated OpenSora-Plan-based talking-face foundation models at 1B/3B/5B scales.
- Built a 1,000+ hour talking-face video database with MLLM-generated captions and multimodal annotations.
- Supported DH-FaceVid-1K and DH-OmniFace dataset construction.
🛠️ Projects
Digital Human Generation Foundation Model R&D
Li Auto – University Joint Program · Jun. 2024 – Jan. 2025
Technical route design, dataset investigation, model reproduction, and experimental validation for a 2D digital human video generation foundation model.
Agent-Based Multilingual MOOC Teaching Video Generation System
Jan. 2026 – Mar. 2026
Multi-agent course video generation pipeline supporting PPT upload or course-topic input, with automatic course structuring, translation verification, voice cloning, digital human generation, video composition, and subtitle export.
🏆 Honors and Awards
- National Scholarship for Doctoral Students, Harbin Institute of Technology, 2026.
- Organizer, ACM Multimedia Asia 2025 Grand Challenge: Multimodal Multiethnic Talking-Head Video Generation.
📚 Academic Services
- Journal reviewer: IEEE Transactions on Multimedia (TMM), Neurocomputing, Pattern Recognition, Knowledge-Based Systems, Neural Networks, and Chinese Journal of Computers (计算机学报).
- Conference reviewer: ACM Multimedia (ACM MM), AAAI, NeurIPS, CVPR, ICLR, ICML, ICASSP, ICME, and the International Conference on Multimedia Modeling (MMM).
🛠️ Skills
- Programming: Python, PyTorch, Linux, Git, Docker, LaTeX
- Research methods: diffusion transformers, vision-language models, and benchmark design for video generation
- Languages: Chinese, English
Visitor Statistics
— unique visitors · — page views